Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Devin for Chip Design.
Autoreduce is distributed autoresearch for ML systems, helping agents discover both the best algorithms and the GPU scale where they work best.
xLift is a pre-training data scout which predicts which cohorts will move a model before we spend compute. Our differentiator is that we measure whether the cohort creates learnable disagreement.
Start thousands of parallel agents in under 500ms. sui clones any git repository in under 1 second and creates worktrees in 100ms
Let the consumers label the data.
self-customizing personal companion directly in your browser and mobile.
Docker infrastructure for memory and context in AI agents
Ads are broken for AI chat. We let advertisers bid for test-time compute, not attention: relevant products buy the agent more reasoning to prove they fit your private context.
A jailbreak detector that escalates compute only when unsure, beating always-on detection by 2pts recall at 1.6x less compute on JailbreakBench.
Komachi AI combines your health records, local real-world data, and global medical evidence to provide personalized guidance for safer alcohol consumption decisions that protect your future health.
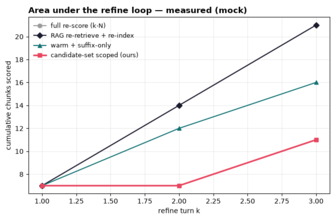
FlashGrep replaces RAG indexes with live LLM semantic scoring. It caches results so users/agents can refine instantly, add fresh data, and search large corpora faster as compute scales.
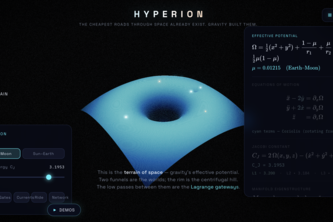
The cheapest roads through space already exist. Gravity built them. We just couldn't afford to find them... until now.
Verified, hands-free first aid: a frozen open model pushed to 98% with inference-time compute, never an unverified step.
Alpha Go moment for Clash Royale
The future of compute is shared latent state. Our demo shows what happens when bandwidth carries meaning instead of pixels, and edge devices stop wasting silicon on duplicated work.
Cell signaling is attention. We simulate tissue as transformer forward passes, a physics engine for biology where you drop in cancer or a virus, native on transformer silicon.
Never let an AI repeat a workflow twice - let a stronger coding agent solve the problem and distill this knowledge to a 10x cheaper and 10x faster open-source model overnight.
A test-time-adaptive compiler that burns a tiny neural network onto a real FPGA, using synthesis/simulation feedback to improve the hardware config for that exact model and board.
Text-based memory is inefficient and wastes context. We use hypernetworks (Doc-to-LoRA) to allow agents to edit their own parameters at inference time, applied to memory, personalization, and skills.
Breaking Online-Softmax Dependencies for Long-Context Decode
Project Falcon makes long-context AI cheaper and more reliable: same hardware, half the memory budget, better answers.
Orchestration on coding agent Watch it. Checkpoint it. Retry it — smarter & cheaper.
Sandra is an AI agent for bioinformatics, automating folding, sequence analysis, and research pipelines so scientists go from question to result in minutes, not weeks :)
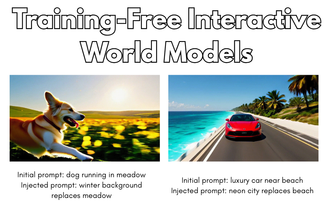
Turn your world model interactive without training.
1 – 24 of 47