Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
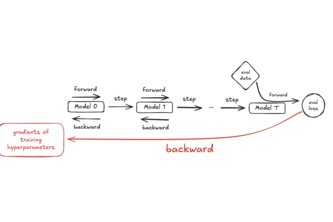
Metagradients for data filtering. Optimized w/ TK kernels & distilled metagrad-approximator model.
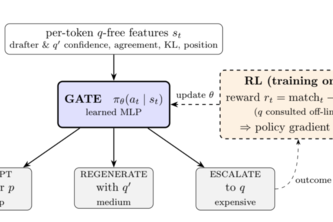
S4D is a state-of-the-art hierarchical speculative decoding method that replaces hand-tuned speculative-decoding thresholds with a learned per-token routing policy
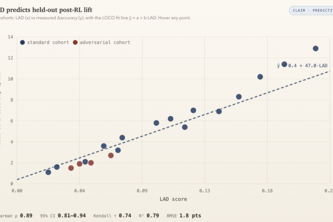
LAD predicts whether RL data will improve a model before costly training, using only a few rollouts per task, no gradients, to deliver cheap, accurate lift forecasts where costly proxies fall short.
A multi-agent harness Cli bump Devin with Opus 4.8 on Swe-Bench pro from 50% to 70%
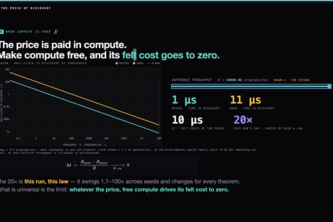
With infinite compute, what is knowledge worth? We measured it: stripped of semantic clues, an LLM needs ~12–20× more inference to rediscover natural law—a price that falls to zero as compute scales.
We introduce a hedge fund run by a fleet of small LLMs that write their own trading strategies as code and ship them in milliseconds. Tap to buy in, watch it beat typical buy-and-old in real-time.
Organizing physical human intelligence.
.
Vending machines that stay profitable - Bankruptcy-gated vending sim with in-world turn cost, plus a genetic outer loop that maintains diverse operating postures under selection pressure.
Financial Superintelligence
cheaper RL through reasoning trace distillation
pushing on-device inference beyond its limits
Adaptive AI red-teamer agent that poisons a coding agent's context to surface unsafe-merge vulnerabilities, scored by an LLM judge.
Emoji-to-emoji diffusion: a low-dimensional proxy for text that reasons in parallel, not word-by-word. A 328M model that tops the frontier at emoji infill—and scales with compute.
DistEvaL is an evaluation framework for AI agents that automatically identifies where an agent is inconsistent, and turns those inconsistencies into usable training data that helps re-train the agent.
A self-improving predictor that tells you if RL data will improve your model, without needing to actually train.
Qssessment turns job requirements into interactive AI interviews that test how candidates ask questions and reason through ambiguity.
We give every student a real-time AI tutor that detects confusion during class and instantly provides personalized explanations before they fall behind.
An interactive book-to-video platform - highlight any passage and get a cinematic clip that's true to the story.
Making clinical trials recruiting easier.
Extreme compression of transformers - diffusion models, LLMs, etc Compressed Sana-1.6B diffusion model from 3.2GB to 0.5GB with little loss in quality!
Spend compute to climb to correct.
25 – 47 of 47